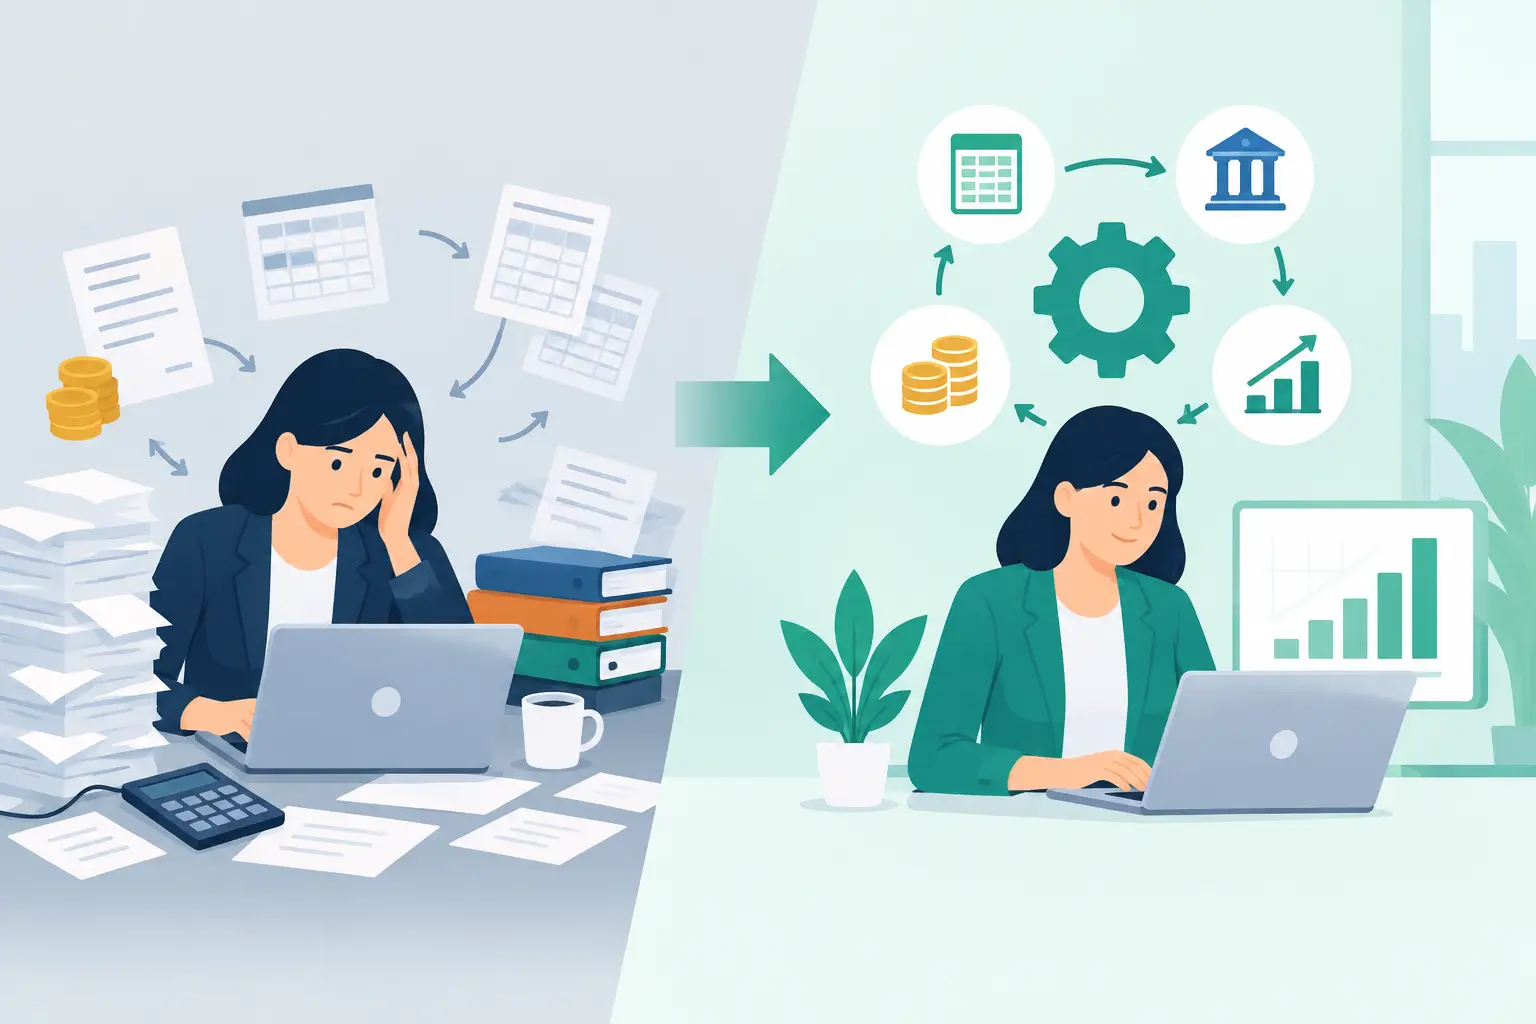
A finance team can appear highly productive while spending most of its capacity correcting data, chasing approvals, and reconciling transactions that should have matched automatically. That was the starting point for this finance automation case study: an operations-heavy manufacturer with growing transaction volumes, multiple ERP instances, and a month-end close dependent on spreadsheets and individual expertise.
The company had already invested in workflow tools and point automation. The problem was not a lack of technology. Its problem was that automation had been applied around fragmented processes and inconsistent data. The result was faster execution of steps that still created exceptions, rework, and control risk.
The operating problem behind the finance backlog
The finance organization processed more than 180,000 supplier invoices annually across five business units. Purchase orders, goods receipts, invoices, and vendor master data were held across connected but inconsistent systems. Accounts payable specialists spent substantial time identifying the correct cost center, resolving duplicate records, and routing invoices to approvers who were often unavailable.
Month-end close amplified the issue. Controllers exported data from separate ledgers, adjusted files manually, and reconciled balances through email-based review cycles. A late invoice, missing receipt, or inconsistent entity code could create several downstream tasks. Finance leadership lacked a reliable real-time view of open exceptions, accrued liabilities, or close readiness.
The business had set clear operational objectives: reduce manual invoice handling, shorten the close cycle, improve auditability, and provide finance leaders with a shared view of process performance. These objectives could not be met by deploying bots alone. The underlying workflow first had to be organized around consistent rules, ownership, and data.
Finance automation case study: redesign before deployment
The transformation began with process discovery across accounts payable, procurement, controlling, and IT. Rather than mapping only the standard invoice flow, the project team analyzed actual variants: invoices without purchase orders, partial goods receipts, recurring service charges, intercompany postings, and vendor-specific exceptions.
This analysis revealed that more than 40 percent of invoices entered an exception path. Some exceptions were legitimate and required human review. Others were caused by avoidable conditions, including incomplete purchase order fields, duplicate vendor records, inconsistent tolerance settings, and unclear approval limits.
The team divided the work into three coordinated tracks: process redesign, data remediation, and automation delivery. This sequence was deliberate. Automating a process with unresolved ownership or unreliable master data would have increased exception volume and created a higher maintenance burden.
Process rules were made explicit
The redesigned invoice process introduced clear routing logic based on purchase order status, invoice value, entity, category, and variance thresholds. Straight-through processing was reserved for transactions that met defined quality and matching criteria. Exceptions were categorized by cause and routed to the team best positioned to resolve them.
This changed the role of accounts payable. Instead of manually touching every invoice, specialists focused on exceptions that required judgment, supplier communication, or policy decisions. Escalation rules also prevented invoices from sitting in approval queues without visibility.
For close activities, the company established a standardized calendar, task ownership model, and evidence requirements. Each task had a defined completion condition rather than an informal status update. This created a controlled workflow that could be measured and improved over time.
Data became a transformation workstream
Vendor master data was consolidated and duplicate records were flagged for remediation. The project also standardized reference fields used to match invoices to purchase orders and goods receipts. Where source data could not be corrected immediately, validation rules identified missing or conflicting information before it reached a downstream process.
A common data model was then used to connect operational transactions with finance reporting. This gave controllers a consistent basis for reviewing exceptions, aging items, accruals, and close status. It also reduced the recurring effort required to reconcile reports created from different systems.
Data work is often treated as a technical prerequisite that can happen in the background. In practice, it is a finance performance initiative. If approval limits, supplier identifiers, cost centers, and transaction statuses mean different things across systems, automation cannot make a process dependable.
The automation architecture
With the redesigned workflow and data rules in place, the organization implemented an integrated automation layer across invoice intake, matching, exception handling, and reporting. Intelligent document processing extracted invoice data and applied validation checks at intake. Workflow automation routed transactions according to the new business rules, while ERP integrations updated records and triggered required actions.
Robotic process automation was used selectively for stable, rule-based work where direct integration was not yet available. This was an intentional trade-off. Bots provided a practical bridge for legacy applications, but the target architecture prioritized APIs and reusable integrations where possible. That reduced long-term dependency on screen-based automation.
A finance operations dashboard brought the process together. Leaders could see invoice volumes by status, exception reasons, approval aging, touchless processing rates, and close task completion in near real time. The dashboard was not treated as a reporting add-on. It was a management tool for identifying bottlenecks, enforcing service levels, and deciding where further process changes were required.
Measurable outcomes after stabilization
Within six months of rollout, the organization increased touchless processing for eligible purchase-order invoices from 28 percent to 71 percent. The remaining manual work was more concentrated in genuine exceptions, rather than routine data entry and routing.
Average invoice handling time fell by 46 percent, while overdue approval queues declined by 62 percent. Because exceptions were categorized consistently, procurement and finance could address recurring causes instead of repeatedly resolving the same symptoms.
The month-end close was shortened from nine business days to six. Equally important, controllers gained earlier visibility into incomplete reconciliations and outstanding approvals. Finance leadership no longer had to wait for final spreadsheet consolidation to understand whether the close was at risk.
Control improved alongside speed. Every workflow decision, approval, and exception resolution was recorded within the process. Audit preparation became less dependent on retrieving evidence from individual inboxes and local files. The company also introduced regular reviews of automation performance, data-quality issues, and process-rule changes to prevent the solution from degrading as operations evolved.
What made the program scalable
The technology was not the sole reason for the result. The program worked because finance, procurement, IT, and process owners operated from one transformation plan. Process decisions were tied to data standards, automation requirements, control design, and reporting measures.
That alignment matters when an enterprise operates across business units or countries. A global template can create consistency, but forcing every local process into identical rules may create resistance or noncompliance. The company therefore standardized core controls, data definitions, and performance measures while allowing limited local variations for tax, regulatory, and operational requirements.
The organization also avoided measuring success only through headcount reduction. Capacity release was a significant benefit, but the more durable value came from better exception management, faster financial visibility, and a process that could absorb higher transaction volumes without proportional staffing growth.
Lessons for finance leaders
The case demonstrates a practical point: finance automation should begin with the work that creates the most avoidable friction, not necessarily the work that appears easiest to automate. High-volume invoice processing was a logical starting point here because it affected working capital, supplier relationships, close performance, and finance capacity.
It also shows why automation priorities should be based on process evidence. Before selecting tools, leaders need to understand transaction variants, exception causes, handoffs, data dependencies, and control requirements. A workflow with a high manual workload may not be the best candidate if its rules are unstable or its input data is unreliable.
For organizations with complex finance environments, the most effective approach connects process improvement, data architecture, automation, and operational measurement. Treating these as separate projects usually shifts problems from one team or system to another.
A strong finance transformation leaves teams with more than faster transactions. It gives them a controlled operating model that makes performance visible, directs expertise to the exceptions that matter, and creates a foundation for the next improvement cycle.